Linked Lists
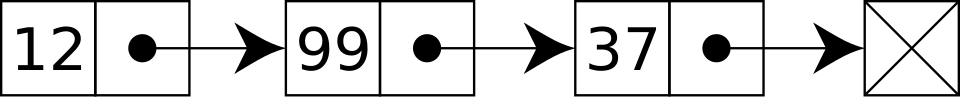
A linked list stores each element in its own node, together with a pointer to the next one. Nothing
is contiguous, so there is no arithmetic that finds element i — you follow pointers from the head
until you arrive.
In exchange, inserting or removing a node costs a couple of pointer assignments regardless of list length, and never moves any other element.
Core Concepts
| Variant | Each node holds | Enables |
|---|---|---|
| Singly linked | next | Forward traversal only |
| Doubly linked | next, prev | Backward traversal; removal given only the node |
| Circular | last node points back to first | Round-robin iteration with no end case |
| Sentinel / dummy head | a permanent empty node at the front | Removes the "is it the first node?" special case from every operation |
Mechanism
The core operations
- Python
- C++
class Node:
    def __init__(self, value, nxt=None):
        self.value = value
        self.next = nxt

# Insert after a node we already hold — O(1), no traversal
def insert_after(node, value):
    node.next = Node(value, node.next)

# Delete the node after a node we hold — O(1)
def delete_after(node):
    if node.next:
        node.next = node.next.next

# Find the nth node — O(n), and this is the catch
def get(head, n):
    while head and n:
        head, n = head.next, n - 1
    return head
struct Node {
    int value;
    Node* next = nullptr;
};

// Insert after a node we already hold — O(1), no traversal
void insert_after(Node* node, int value) {
    node->next = new Node{value, node->next};
}

// Delete the node after a node we hold — O(1)
void delete_after(Node* node) {
    if (node->next) {
        Node* dead = node->next;
        node->next = dead->next;
        delete dead;
    }
}

// Find the nth node — O(n), and this is the catch
Node* get(Node* head, int n) {
    while (head && n) {
        head = head->next;
        --n;
    }
    return head;
}
The asymmetry is the whole story. Every operation is given a reference to the right node, and getting that reference is . A linked list only pays off when the traversal was going to happen anyway, or when you were handed the node by something else.
Deleting the middle node, traced
Deleting the node holding 8 from the 4-node list 5 -> 1 -> 8 -> 3 -> None requires the node
before it, because a singly linked list has no way to reach backwards — the predecessor is what
gets its next pointer rewritten, not the node being removed:
start:        5 -> 1 -> 8 -> 3 -> None
              (head)

step 1        walk from head until node.next is the target:
              prev = node(1)          # node(1).next is node(8), the one to remove
              target = node(8)

step 2        prev.next = target.next
              node(1).next = node(3)  # node(8) is now unreachable from the list

result:       5 -> 1 -> 3 -> None
              node(8) still exists in memory until nothing else references it
              (garbage collected in Python; must be freed explicitly in C++)
Exactly one pointer write — prev.next = target.next — does the whole deletion, and its cost does not
depend on which node is removed. Finding prev is the part that costs : reaching the middle of a
4-node list already needs 2 hops, and the general case is worst case (and average case, over
a target position chosen uniformly at random). A doubly linked list would remove the need to walk
from the head at all if a reference to the target itself is already held, since target.prev gives the
predecessor directly — the reason OrderedDict-style caches use one:
- Python
- C++
def delete_value(head, value):
    """Delete the first node holding `value`. Returns the (possibly new) head."""
    if head is None:
        return None
    if head.value == value:
        return head.next                # deleting the head needs no predecessor
    prev = head
    while prev.next and prev.next.value != value:
        prev = prev.next
    if prev.next:
        prev.next = prev.next.next      # the one pointer write that does the deletion
    return head

n4 = Node(3)
n3 = Node(8, n4)
n2 = Node(1, n3)
n1 = Node(5, n2)
new_head = delete_value(n1, 8)
result = []
node = new_head
while node:
    result.append(node.value)
    node = node.next
assert result == [5, 1, 3]
Node* delete_value(Node* head, int value) {
    if (!head) return nullptr;
    if (head->value == value) {
        Node* rest = head->next;
        delete head;                    // deleting the head needs no predecessor
        return rest;
    }
    Node* prev = head;
    while (prev->next && prev->next->value != value) prev = prev->next;
    if (prev->next) {
        Node* target = prev->next;
        prev->next = target->next;      // the one pointer write that does the deletion
        delete target;
    }
    return head;
}
Why a sentinel node simplifies the code
Without one, inserting or deleting at the head is a special case, because there is no predecessor to
update — so every function grows an if node is head branch. A permanent dummy node in front means
every real node has a predecessor and the special case disappears. It costs one node of memory and
removes the most common source of off-by-one bugs in list code.
Two-pointer techniques
Linked lists are where the two-pointer pattern earns its keep, because you cannot index:
- Python
- C++
# Middle of the list in one pass: fast moves twice per slow step
def middle(head):
    slow = fast = head
    while fast and fast.next:
        slow, fast = slow.next, fast.next.next
    return slow

# Cycle detection (Floyd's algorithm): if there is a loop, fast laps slow
def has_cycle(head):
    slow = fast = head
    while fast and fast.next:
        slow, fast = slow.next, fast.next.next
        if slow is fast:
            return True
    return False
// Middle of the list in one pass: fast moves twice per slow step
Node* middle(Node* head) {
    Node* slow = head;
    for (Node* fast = head; fast && fast->next; fast = fast->next->next)
        slow = slow->next;
    return slow;
}

// Cycle detection (Floyd's algorithm): if there is a loop, fast laps slow
bool has_cycle(Node* head) {
    Node* slow = head;
    Node* fast = head;
    while (fast && fast->next) {
        slow = slow->next;
        fast = fast->next->next;
        if (slow == fast) return true;
    }
    return false;
}
Practical Usage
Where linked lists genuinely win:
- LRU caches — a hash table maps key → node, and the doubly linked list maintains recency. The hash table supplies the node reference in , so the list's splice is actually reachable. This is the pattern that makes linked lists worth knowing.
- Intrusive lists in kernels and allocators — the node fields live inside the object itself, so
an object can remove itself from a list without any lookup or allocation. Linux's
list_headis the canonical example. - Structures built from nodes anyway — the chains in a hash table with separate chaining, or free lists in an allocator.
Edge Cases & Pitfalls
Traversing a linked list is a dependent load chain: the address of the next node is not known until the current one arrives from memory, so the CPU cannot prefetch and cannot overlap the misses. A sequential array scan of the same elements issues independent loads that the hardware prefetcher handles perfectly.
The practical consequence is that "insertion is , so use a list" is usually wrong. Inserting into
a vector means an memmove, which modern hardware performs at many gigabytes per second;
finding the insertion point in a list means n cache misses at ~100 ns each. For anything short of
enormous, the array wins — including on the operation the list is supposed to be good at.
std::list::size()was in some pre-C++11 implementations. The standard now requires , but the anecdote is a reminder to check what your library actually guarantees.- Reversing or sorting a list is doable in and respectively, but the constant factors are poor. Copy into an array, operate, copy back — this is frequently faster.
- Memory overhead is real. A singly linked list of 8-byte integers on a 64-bit machine spends 8 bytes on the pointer and typically another 8–16 on allocator bookkeeping per node — a 3× or worse memory penalty over an array, which then costs you again in cache pressure.
Comparisons
| Operation | Array | Singly linked | Doubly linked |
|---|---|---|---|
| Access by index | |||
| Insert/delete at front | |||
| Insert/delete at back | amortized | without a tail pointer | with a tail pointer |
| Insert/delete given the node | after the previous node | ||
| Memory per element | Element only | Element + 1 pointer | Element + 2 pointers |
Recall
References
- Cormen, Leiserson, Rivest & Stein, Introduction to Algorithms, §10.2 — linked lists, sentinels, and the operations above.
- Linux kernel
list.h— the intrusive doubly-linked circular list used throughout the kernel.
Books & Videos
- Bjarne Stroustrup, "Why you should avoid Linked Lists" — the short talk behind the pitfall above, with measurements.
Related Pages
- Arrays & Dynamic Arrays — the alternative, and usually the right one.
- Stacks & Queues — commonly built on either representation.
- Hash Tables — where chained linked lists appear inside another structure.