Prefix Sums & Difference Arrays
Summing a range of an array costs time proportional to the range. Do it once and nobody notices; do it over each of the possible ranges and an inner sum that is in the worst case makes the whole enumeration worst case. The fix is not a cleverer summing loop. It is to sum once, up front, and store the running total, so that every later question is answered by arithmetic on two stored numbers instead of by touching the data at all.
That is the whole pattern: precomputation trades one linear pass now for constant-time answers
later. The stored array P is a running total — P[i] is the sum of everything before index i —
so the sum over [l, r] is whatever accumulated by the end of r minus whatever had accumulated
before l, with the elements in between cancelling exactly once. The same cancellation works for any
operation with an inverse: XOR (its own inverse), counts, products over a field. It does not work
for min or max — nothing undoes a maximum.
A difference array is the same identity read backwards. If prefix-summing D reconstructs a,
then editing D at two positions edits a whole range of a: D[l] += v and D[r+1] -= v add v to
every element of a[l..r] in worst case, with the prefix pass paid once at the end. Prefix
sums make reads cheap and writes expensive; difference arrays do the reverse — pick the side you have
more of.
Core Concepts
| Term | Meaning |
|---|---|
Prefix array P | P[0] = 0, P[i] = P[i−1] + a[i−1]. Length n + 1 — the leading zero is not optional |
| Inclusive range sum | sum(l, r) = P[r+1] − P[l] |
2-D prefix P[i][j] | Sum of the rectangle from the origin to (i−1, j−1) |
| Inclusion–exclusion | The 2-D query subtracts two strips and adds back the corner counted twice |
Difference array D | D[i] = a[i] − a[i−1]. Prefix-summing D reproduces a |
| Prefix XOR / prefix count | The same identity under a different invertible operation |
Mechanism
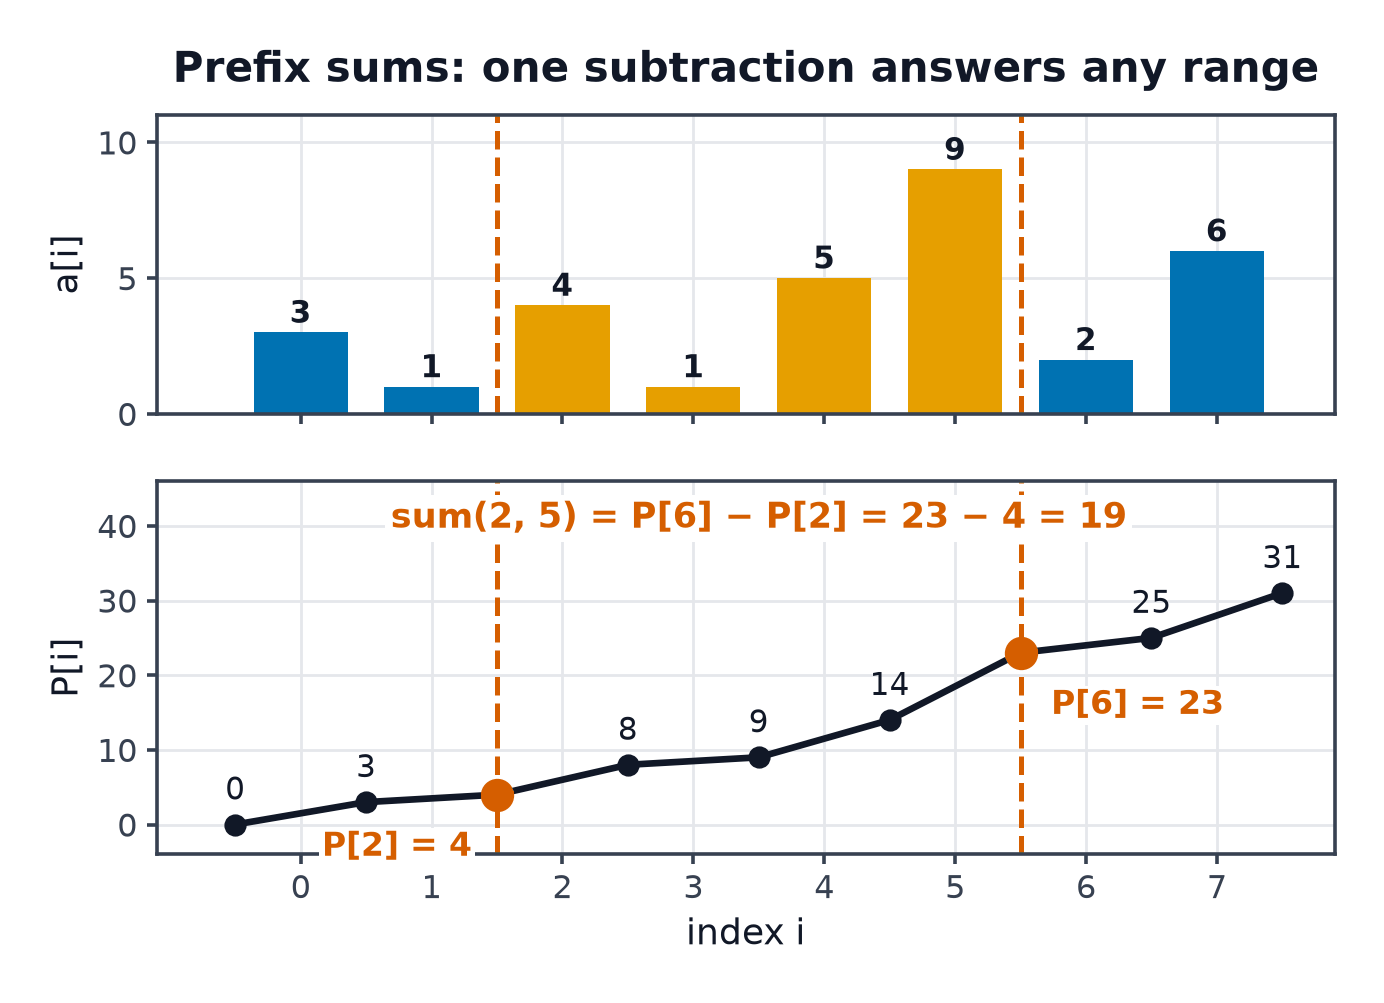
a = [3, 1, 4, 1, 5, 9, 2, 6]

  i    a[i]    P[i+1] = P[i] + a[i]
  -    -       P[0] = 0
  0    3       3
  1    1       4
  2    4       8
  3    1       9
  4    5       14
  5    9       23
  6    2       25
  7    6       31

sum(2, 5) = P[6] − P[2] = 23 − 4 = 19   (4 + 1 + 5 + 9 = 19 ✓)
Read the indices carefully. P[2] is the total before index 2, so it excludes a[2] — what you
want on the left. P[6] is the total before index 6, so it includes a[5] — what you want on the
right. And sum(0, r) is P[r+1] − P[0], which needs no special case because P[0] is 0.
- Python
- C++
def build_prefix(a):
    """P has length len(a) + 1; P[0] = 0 is what removes every boundary special case."""
    p = [0] * (len(a) + 1)
    for i, value in enumerate(a):
        p[i + 1] = p[i] + value
    return p


def range_sum(p, lo, hi):
    """Inclusive [lo, hi]."""
    return p[hi + 1] - p[lo]


A = [3, 1, 4, 1, 5, 9, 2, 6]
P = build_prefix(A)
assert P == [0, 3, 4, 8, 9, 14, 23, 25, 31]
assert range_sum(P, 2, 5) == 19
assert range_sum(P, 0, 7) == sum(A)     # the whole array, no special case
#include <cassert>
#include <numeric>
#include <vector>

std::vector<long long> build_prefix(const std::vector<int>& a) {
    std::vector<long long> p(a.size() + 1, 0);   // long long: the sum outgrows int
    for (std::size_t i = 0; i < a.size(); ++i) p[i + 1] = p[i] + a[i];
    return p;
}

long long range_sum(const std::vector<long long>& p, std::size_t lo, std::size_t hi) {
    return p[hi + 1] - p[lo];                    // inclusive [lo, hi]
}
Two dimensions
P[i][j] is the sum of the rectangle from the origin up to but excluding row i and column j.
Building it is the same running total applied twice, with the doubly-counted overlap removed; a query
is inclusion–exclusion over four corners. Building is worst case, every query afterwards .
- Python
- C++
def build_prefix_2d(g):
    rows, cols = len(g), len(g[0])
    p = [[0] * (cols + 1) for _ in range(rows + 1)]
    for i in range(rows):
        for j in range(cols):
            #        this cell    strip above     strip left    counted twice
            p[i + 1][j + 1] = g[i][j] + p[i][j + 1] + p[i + 1][j] - p[i][j]
    return p


def rect_sum(p, r1, c1, r2, c2):
    """Inclusive rectangle [r1..r2] x [c1..c2]: everything, minus two strips, plus the corner."""
    return p[r2 + 1][c2 + 1] - p[r1][c2 + 1] - p[r2 + 1][c1] + p[r1][c1]


GRID = [[3, 1, 4], [1, 5, 9], [2, 6, 5]]
P2 = build_prefix_2d(GRID)
assert rect_sum(P2, 1, 1, 2, 2) == 25                     # 5 + 9 + 6 + 5, the bottom-right block
assert rect_sum(P2, 0, 0, 2, 2) == sum(map(sum, GRID))
using Grid = std::vector<std::vector<long long>>;

Grid build_prefix_2d(const Grid& g) {
    Grid p(g.size() + 1, std::vector<long long>(g[0].size() + 1, 0));
    for (std::size_t i = 0; i < g.size(); ++i)
        for (std::size_t j = 0; j < g[0].size(); ++j)
            p[i + 1][j + 1] = g[i][j] + p[i][j + 1] + p[i + 1][j] - p[i][j];
    return p;
}

long long rect_sum(const Grid& p, std::size_t r1, std::size_t c1, std::size_t r2, std::size_t c2) {
    return p[r2 + 1][c2 + 1] - p[r1][c2 + 1] - p[r2 + 1][c1] + p[r1][c1];
}
Difference arrays
Deferring the reads inverts the costs: each range update is two writes, and the array is materialised once at the end.
- Python
- C++
from itertools import accumulate


def range_add(diff, lo, hi, value):
    """Add `value` to every element of a[lo..hi] in O(1) worst case."""
    diff[lo] += value
    diff[hi + 1] -= value          # the guard cell is why diff has n + 1 entries


diff = [0] * (8 + 1)               # n + 1: hi + 1 may be n
range_add(diff, 1, 3, 5)
range_add(diff, 2, 6, -2)
# one O(n) prefix pass turns the recorded deltas back into the array
assert list(accumulate(diff[:8])) == [0, 5, 3, 3, -2, -2, -2, 0]
void range_add(std::vector<long long>& diff, std::size_t lo, std::size_t hi, long long v) {
    diff[lo] += v;
    diff[hi + 1] -= v;                            // diff has n + 1 cells
}

// materialising is one prefix pass, in place:
//   std::partial_sum(diff.begin(), diff.begin() + n, diff.begin());
The variants, in one line each
- Prefix XOR.
X[i] = a[0] ^ … ^ a[i−1], anda[l] ^ … ^ a[r] = X[r+1] ^ X[l]— XOR is its own inverse, so the subtraction is another XOR. - Prefix counts. One prefix array per symbol turns "how many
xin[l, r]" into a subtraction, at space — hence small alphabets only. - Prefix products. Undoing multiplication needs division: safe modulo a prime, unsafe over floats.
- Prefix max. Does not work — nothing cancels. Range minimum wants a sparse table.
Practical Usage
Neither language makes you write the accumulation loop.
- Python
- C++
from collections import defaultdict

# accumulate(iterable, function=operator.add, *, initial=None). `initial` was added
# in 3.8 and is exactly the leading zero this pattern needs:
# https://docs.python.org/3/library/itertools.html#itertools.accumulate
assert list(accumulate(A, initial=0)) == P                  # without `initial` there is no P[0]


def count_subarrays_with_sum(a, k):
    """Subarrays summing to k, in one pass — the prefix-sum-in-a-hash-map idiom.

    a[l..r] sums to k exactly when P[r+1] − P[l] == k, so for each running total
    the answer is how many earlier prefixes equal `running − k`.
    """
    seen = defaultdict(int)
    seen[0] = 1                    # the empty prefix, so subarrays starting at 0 count
    total = running = 0
    for value in a:
        running += value
        total += seen[running - k]
        seen[running] += 1
    return total


assert count_subarrays_with_sum(A, 5) == 3     # [1,4], [4,1], [5]
// partial_sum: exactly (last - first) - 1 applications  [partial.sum]
// inclusive_scan / exclusive_scan (C++17): O(last - first) applications, and
// parallelisable — at the price of "if binary_op is not mathematically
// associative, the behavior ... can be nondeterministic"  [inclusive.scan]
void scans(const std::vector<int>& a) {
    std::vector<long long> inclusive(a.size()), exclusive(a.size());
    std::partial_sum(a.begin(), a.end(), inclusive.begin());       // 3 4 8 9 14 ...
    std::exclusive_scan(a.begin(), a.end(), exclusive.begin(), 0LL); // 0 3 4 8 9 ...
    assert(inclusive.back() == 31);
}
Real call sites: cumulative-distribution sampling (build once, binary-search it per sample), integral images for constant-time box filters, per-day running balances, and batch "add v to this window" jobs whose reads all happen after the writes.
Edge Cases & Pitfalls
- Integer overflow in C++. A prefix array outgrows
intlong before the input looks large, and the result is a silently wrong query rather than an error — accumulate intolong long. See integers and two's complement. Python'sintis arbitrary precision, so the failure mode does not exist there. - The stale prefix. Mutating
a[i]after buildingPleaves everyP[j]forj > iwrong and nothing complains — queries return plausible wrong numbers. Mutable data wants a Fenwick or segment tree, at worst case per update. - Off-by-one at the right edge.
P[r] − P[l]is the half-open convention and silently dropsa[r]; mixing it with the inclusive form in one file is the classic quiet wrong answer. The difference array needsn + 1cells for the same reason —hi + 1can ben. - Floating-point drift. A running total over floats accumulates rounding error, so
P[r] − P[l]can differ from summing the slice directly — and the further right the range, the larger the two numbers being subtracted and the more of their precision the subtraction cancels away.math.fsumavoids the loss "by tracking multiple intermediate partial sums" but is not incremental, so it does not build a prefix array cheaply; for float-heavy work prefer a segment tree, which sums pairwise.
Comparisons
| Prefix sums | Difference array | Fenwick / segment tree | Recompute each query | |
|---|---|---|---|---|
| Build | worst | worst | worst | — |
| Range query | worst | — materialise first | worst | worst |
| Point update | worst — rebuild | worst | worst | worst |
| Range update | worst | worst | worst | worst |
| Extra space | none |
The decision is the read/write mix: all reads, prefix sums; all writes with one read at the end, a difference array; interleaved, a Fenwick tree — the is the price of not knowing the order.
Recall
References
- Sedgewick & Wayne, Algorithms, 4th ed., §1.4 "Analysis of Algorithms" — the cost model this pattern argues with, using three-sum as the worked enumeration made cheaper by precomputation.
itertools.accumulate— CPython docs; note theinitialkeyword added in 3.8.[partial.sum]and[inclusive.scan]— the C++ standard's own wording for the scan algorithms, including the associativity caveat.
Related Pages
- Two Pointers & Sliding Window — the other way to kill an range enumeration, for contiguous, monotone ranges.
- Problem-Solving Patterns — where this pattern sits among the others.
- Arrays — the contiguous layout that makes the build a single cache-friendly pass.
- Integers & Two's Complement — the overflow that silently corrupts a C++ prefix array.
- Segment Trees & Fenwick Trees — what to reach for once the array starts changing.