Selection Sort
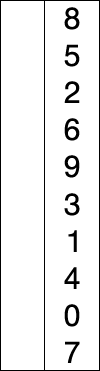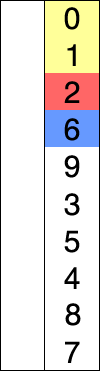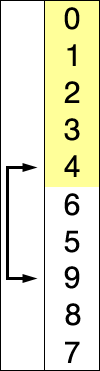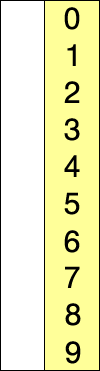
Selection sort divides the array into a sorted prefix and an unsorted remainder. Each round it scans the entire remainder for the smallest element and swaps it into place at the boundary, growing the sorted prefix by one.
It has exactly one genuinely distinguishing property, and the rest of this page exists to isolate it: selection sort performs exactly n − 1 writes, the minimum possible for a comparison sort that moves elements by exchanging them. Every other quadratic sort on this page's siblings writes more — bubble sort writes once per inversion, insertion sort shifts once per inversion too, both of which can be writes on an adversarial input. Selection sort never writes more than n − 1 times regardless of the input, because it commits to at most one swap per round and there are exactly n − 1 rounds that can still find a smaller element ahead of them.
That is the entire case for the algorithm. It buys the minimal write count by giving up everything
else: it cannot finish early on sorted input, it is not stable, and its comparison count is fixed at
n(n−1)/2 no matter what the data looks like. When writes are cheap — the ordinary case on a modern
CPU with a fast cache — selection sort loses to insertion sort on every input. It wins only when reads
are cheap and writes are the expensive resource.
Core Concepts
| Property | Value |
|---|---|
| Best case | — no early exit is possible; the inner scan is unconditional |
| Average | |
| Worst case | |
| Space | |
| Stable | No (in the standard swap-based form) |
| Adaptive | No — sorted input costs exactly as much as random input |
| Writes | exactly n − 1 — the minimum possible for an exchange-based sort |
Mechanism
- Python
- C++
def selection_sort(a):
    n = len(a)
    for i in range(n - 1):
        smallest = i
        for j in range(i + 1, n):        # scan the unsorted remainder
            if a[j] < a[smallest]:
                smallest = j
        if smallest != i:
            a[i], a[smallest] = a[smallest], a[i]    # at most one write per round
    return a
#include <cassert>
#include <utility>
#include <vector>

void selection_sort(std::vector<int>& a) {
    int n = static_cast<int>(a.size());
    for (int i = 0; i < n - 1; ++i) {
        int smallest = i;
        for (int j = i + 1; j < n; ++j)          // scan the unsorted remainder
            if (a[j] < a[smallest]) smallest = j;
        if (smallest != i)
            std::swap(a[i], a[smallest]);        // at most one write per round
    }
}
The comparison count is fixed at n(n−1)/2 regardless of input — the inner loop always runs to the
end, because you cannot know an element is the minimum until you have seen every remaining candidate.
This is why there is no best case and no adaptivity: the comparisons are not the thing this algorithm
optimises.
Tracing [5, 1, 8, 3]:
| Round | Unsorted remainder scanned | Minimum found | Swap | Result | Writes so far |
|---|---|---|---|---|---|
| start | — | — | — | [5, 1, 8, 3] | 0 |
| 1 | [5, 1, 8, 3] | 1 at index 1 | 5 ↔ 1 | [1, 5, 8, 3] | 1 |
| 2 | [5, 8, 3] | 3 at index 3 | 5 ↔ 3 | [1, 3, 8, 5] | 2 |
| 3 | [8, 5] | 5 at index 3 | 8 ↔ 5 | [1, 3, 5, 8] | 3 |
Three rounds, three swaps — n − 1 = 3 for n = 4, exactly as guaranteed, even though the array
needed several elements to move past each other to reach sorted order. Compare this to bubble sort on
the same input, which needed three swaps too here but whose swap count tracks the inversion count of
the input and can reach n(n−1)/2 on a worse one; selection sort's write count never moves.
Why it is not stable
Swapping a distant minimum into position jumps it over intervening elements, which can reorder equal
values. With [2a, 2b, 1] (subscripts marking two equal keys), the first round swaps 1 with 2a,
giving [1, 2b, 2a] — the two 2s have exchanged their original relative order.
Stability is recoverable by shifting the intervening block instead of swapping, but that costs writes per round and forfeits the algorithm's only advantage — a stable selection sort is no longer a minimal-write sort.
Practical Usage
The reason to choose selection sort is when writes are far more expensive, slower, or more limited than reads — a genuinely narrow niche, but a real one:
- EEPROM and flash memory have limited erase/write endurance (each cell tolerates a bounded number
of writes before it wears out) and writes are markedly slower than reads. See
SSDs & NAND Flash — minimising writes is the whole design
pressure there, and a sort that performs
n − 1writes instead of can be the difference between acceptable wear and a burned-out device on a large, frequently-resorted dataset. - Very large records with small keys, where each move copies a lot of bytes. Though in that case the better answer is usually to sort an array of indices or pointers instead (see Choosing a Sort's "sort keys, not records" note), and permute the records once at the end — which makes the number-of-record-writes argument moot for any sort, selection included.
- A hard upper bound on writes is a correctness requirement, not just a performance preference — for instance, a write-once medium, or an audit log that must record no more than n − 1 element relocations.
Outside those cases, insertion sort's shift-based approach is faster in practice on every input shape, because a shift is cheap relative to a full swap and insertion sort additionally finishes early on nearly-sorted data.
- Python
- C++
# checked on the traced input: exactly n - 1 = 3 writes for n = 4
assert selection_sort([5, 1, 8, 3]) == [1, 3, 5, 8]
assert selection_sort([1, 2, 3]) == [1, 2, 3]     # still costs the full n(n-1)/2 comparisons
assert selection_sort([]) == []
int main() {
    std::vector<int> a{5, 1, 8, 3};
    selection_sort(a);
    assert((a == std::vector<int>{1, 3, 5, 8}));
}
Edge Cases & Pitfalls
- No early exit exists. Adding a "did anything change?" check does nothing, because the inner scan is unconditional — every round scans to the end of the remainder regardless of how sorted the data already is. Sorted input costs full price, unlike bubble or insertion sort.
- Assuming it is stable because it looks like it should be. It is not, and the failure appears only when sorting by a secondary key — the exact scenario where stability matters and where the bug is easy to miss in testing.
- Selection sort and heapsort are the same idea, with one substitution. Both repeatedly extract the extreme from the unsorted region; heapsort just uses a heap to find it in instead of , which is exactly what converts into — at the cost of the minimal-write guarantee, since sift-down after each extraction can perform more than one write.
- Treating "minimal writes" as "minimal work". The comparison count is unchanged from the naive quadratic bound; only the write count improves. On a system where reads and writes cost the same, this buys nothing.
Comparisons
| Selection | Bubble | Insertion | |
|---|---|---|---|
| Comparisons (worst) | n(n−1)/2 always | , if sorted | , if nearly sorted |
| Writes (worst) | exactly n − 1 swaps | swaps | shifts |
| Best case | |||
| Stable | No | Yes | Yes |
| Choose when | Writes dominate cost (flash/EEPROM) | Never | Small or nearly-sorted input |
Recall
References
- Cormen, Leiserson, Rivest & Stein, Introduction to Algorithms, 4th ed., Exercise 2.2-2 — selection sort, including the question of why the loop runs to n − 1 rather than n.
- Sedgewick & Wayne, Algorithms, 4th ed., §2.1 — elementary sorts, with the write-count comparison against insertion sort made explicitly.
Books & Videos
- VisuAlgo — Sorting — compare the swap counts against the other elementary sorts on identical input.
Related Pages
- Heapsort — selection sort with a heap doing the selection, trading the minimal-write guarantee for selection instead of .
- Insertion Sort — the elementary sort to reach for by default, when writes are not the bottleneck.
- Bubble Sort — the other elementary sort kept for its lesson rather than its speed.